Subhashree Radhakrishnan

Subhashree Radhakrishnan

I am a Member of Technical Staff at Hark, working on multimodal AI and agents that connect perception, reasoning, and action.

My current work spans vision-language models (VLMs), computer-use agents, reinforcement learning, and self-improving agent systems.

Across my work, I focus on designing and scaling vision-language, video-language, and agentic systems, with a strong emphasis on 0→1 development—identifying the right problem, building the system, and taking it toward real-world deployment.

Previously, I was a Tech Lead and Applied AI Researcher at NVIDIA, where I led initiatives including NVCLIP, a multimodal foundation model for vision-language understanding; LITA, a Language-Instructed Temporal Localization Assistant for video reasoning; and 3D-Layout-R1, for structured spatial reasoning in 3D environments. I also led efforts to build reasoning agents for interactive gaming environments. My earlier work includes DiscoBox, an approach to weakly supervised segmentation.

My research interests include multimodal reasoning, continual learning, spatial and scene understanding, and agentic AI systems that integrate perception with decision-making and improve through interaction.

Prior to NVIDIA, I completed my Master’s at Virginia Tech, where I worked on human-object interaction in videos under the guidance of Prof. Jia-Bin Huang.
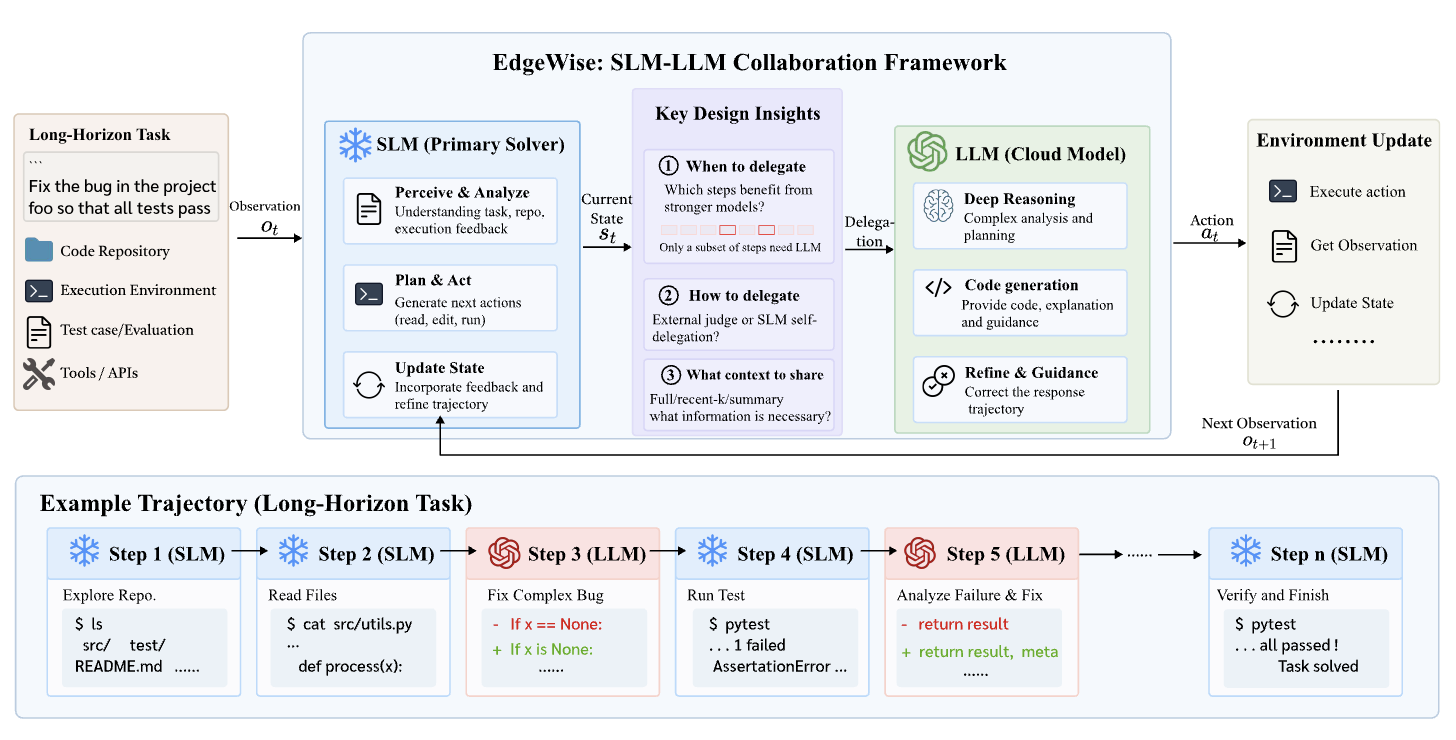
EdgeWise

EdgeWise: Bringing Long-Horizon Agents to the Edge via Selective Cloud Delegation

Zeru Shi, Jindong Jiang, Ryo Hachiuma, Yonggan Fu, Byung-Kwan Lee, Peter Belcak, Saurav Muralidharan, Ayush Agarwal, Ruixiang Tang, Ambrish Dantrey, Pavlo Molchanov, Anjul Patney, Subhashree Radhakrishnan

arXiv 2026

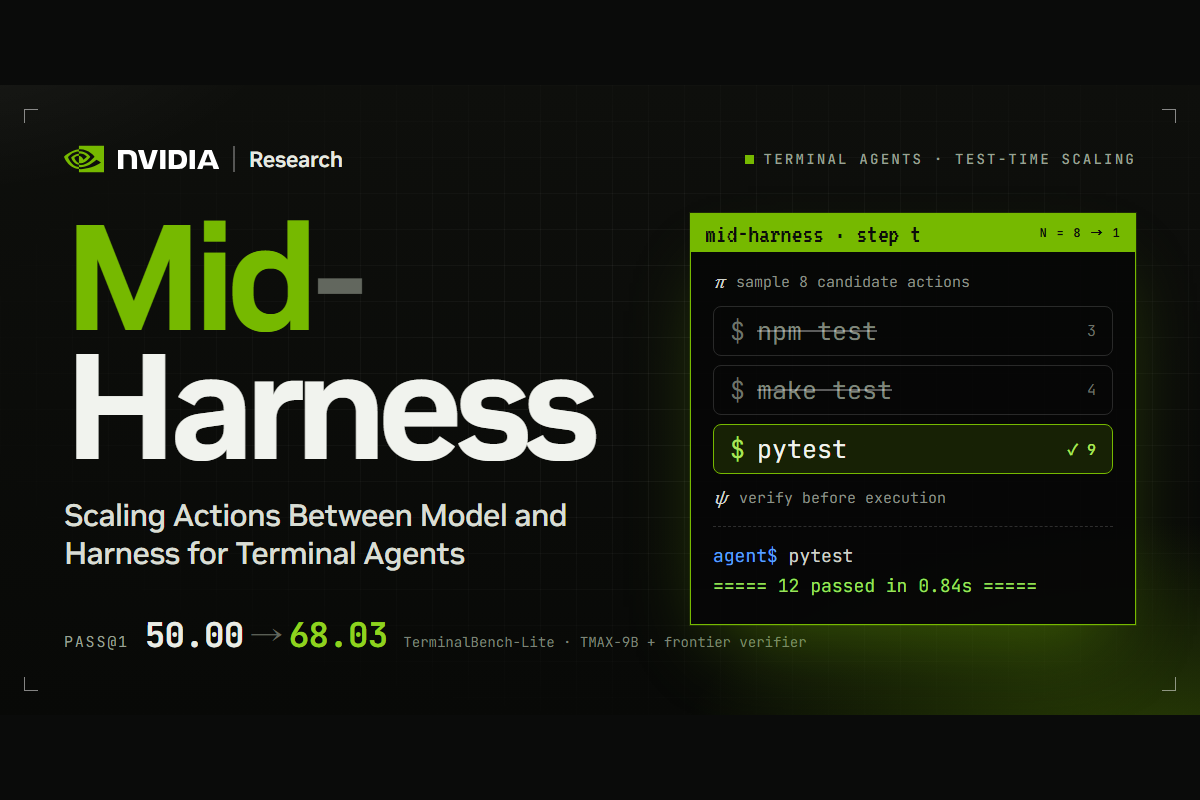
Mid-Harness

Mid-Harness: Scaling Actions Between Model and Harness for Terminal Agents

Minki Kang, Ryo Hachiuma, Shaokun Zhang, Subhashree Radhakrishnan, Yonggan Fu, Jindong Jiang, Mingjie Liu, Ehsan Hosseini-Asl, Yi Dong, Yu-Chiang Frank Wang, Byung-Kwan Lee

arXiv 2026

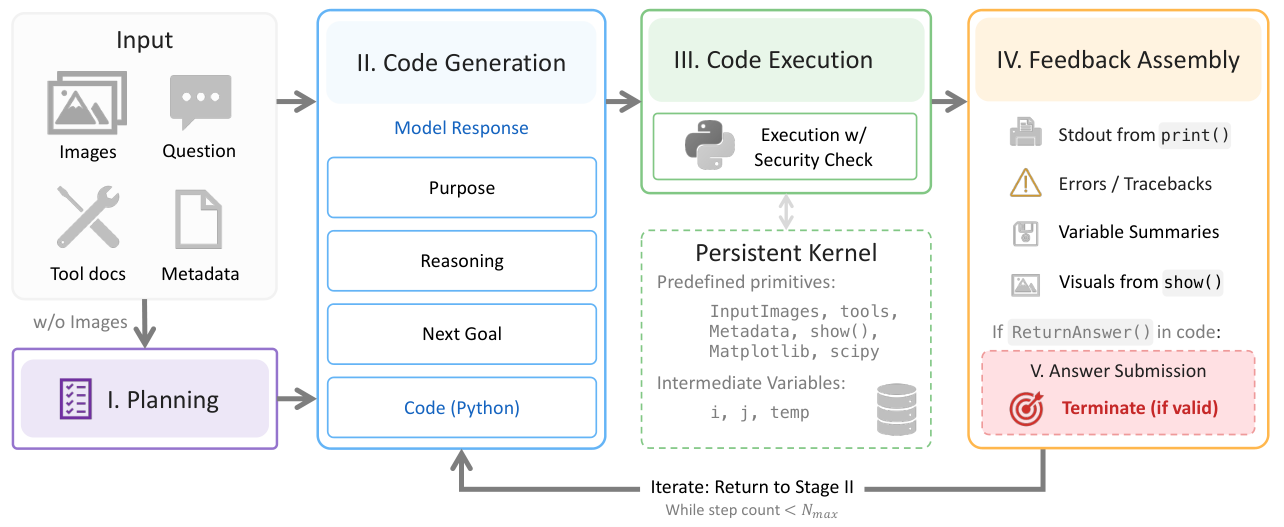
SpatialClaw

SpatialClaw: Rethinking Action Interface for Agentic Spatial Reasoning

Seokju Cho, Ryo Hachiuma, Abhishek Badki, Hang Su, Byung-Kwan Lee, Chan Hee Song, Sifei Liu, Subhashree Radhakrishnan, Seungryong Kim, Yu-Chiang Frank Wang, Min-Hung Chen

arXiv 2026

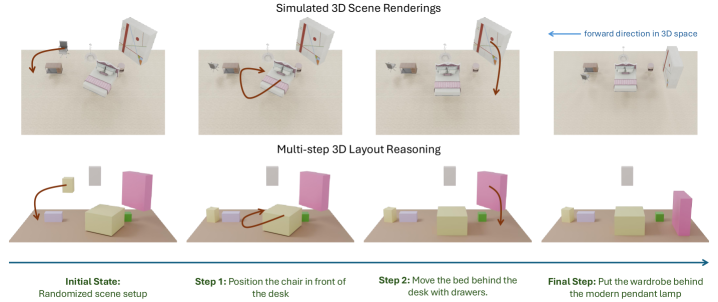
3D-Layout-R1

3D-Layout-R1: Structured Reasoning for Language-Instructed Spatial Editing

Haoyu Zhen, Xiaolong Li, Yilin Zhao, Han Zhang, Sifei Liu, Kaichun Mo, Chuang Gan, Subhashree Radhakrishnan

arXiv 2026

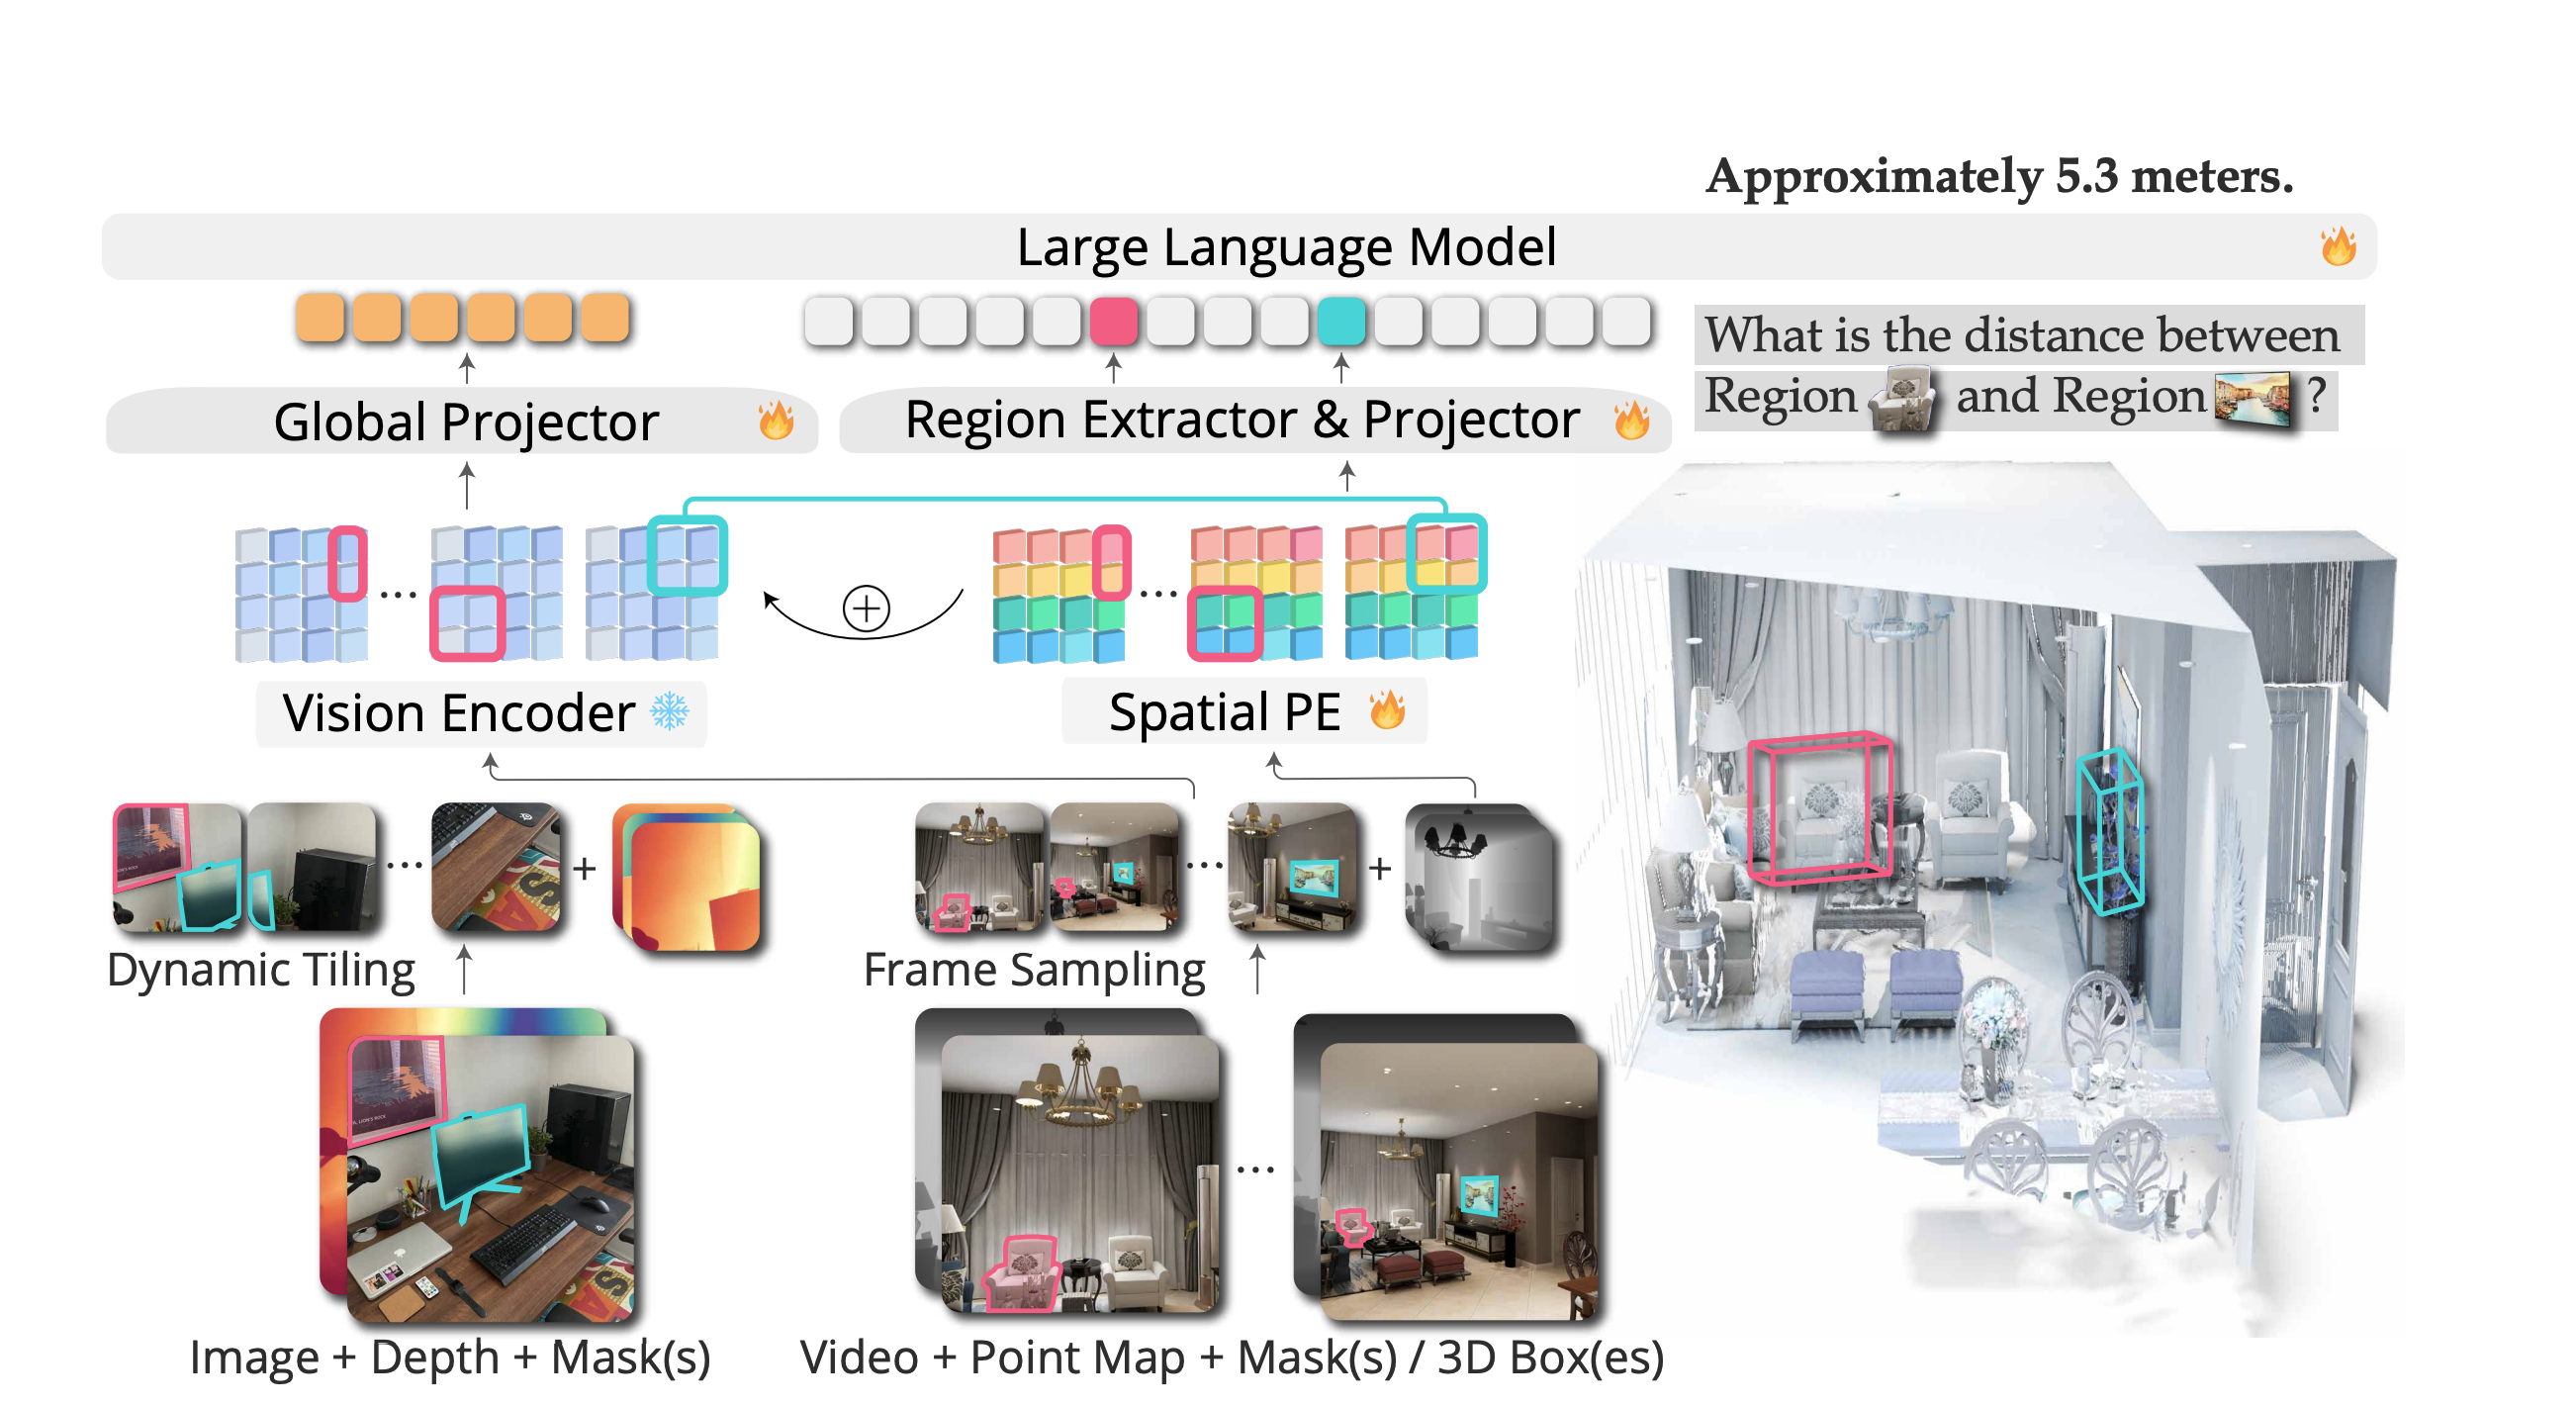
3D-Aware Region-Prompted VLM

3D Aware Region Prompted Vision Language Model

An-Chieh Cheng, Yang Fu, Yukang Chen, Zhijian Liu, Xiaolong Li, Subhashree Radhakrishnan, Song Han, Yao Lu, Jan Kautz, Pavlo Molchanov, Hongxu Yin, Xiaolong Wang, Sifei Liu

ICLR 2026

4D-RGPT

4D-RGPT: Toward Region-level 4D Understanding via Perceptual Distillation

Chiao-An Yang, Ryo Hachiuma, Sifei Liu, Subhashree Radhakrishnan, Raymond A Yeh, Yu-Chiang Frank Wang, Min-Hung Chen

CVPR 2026

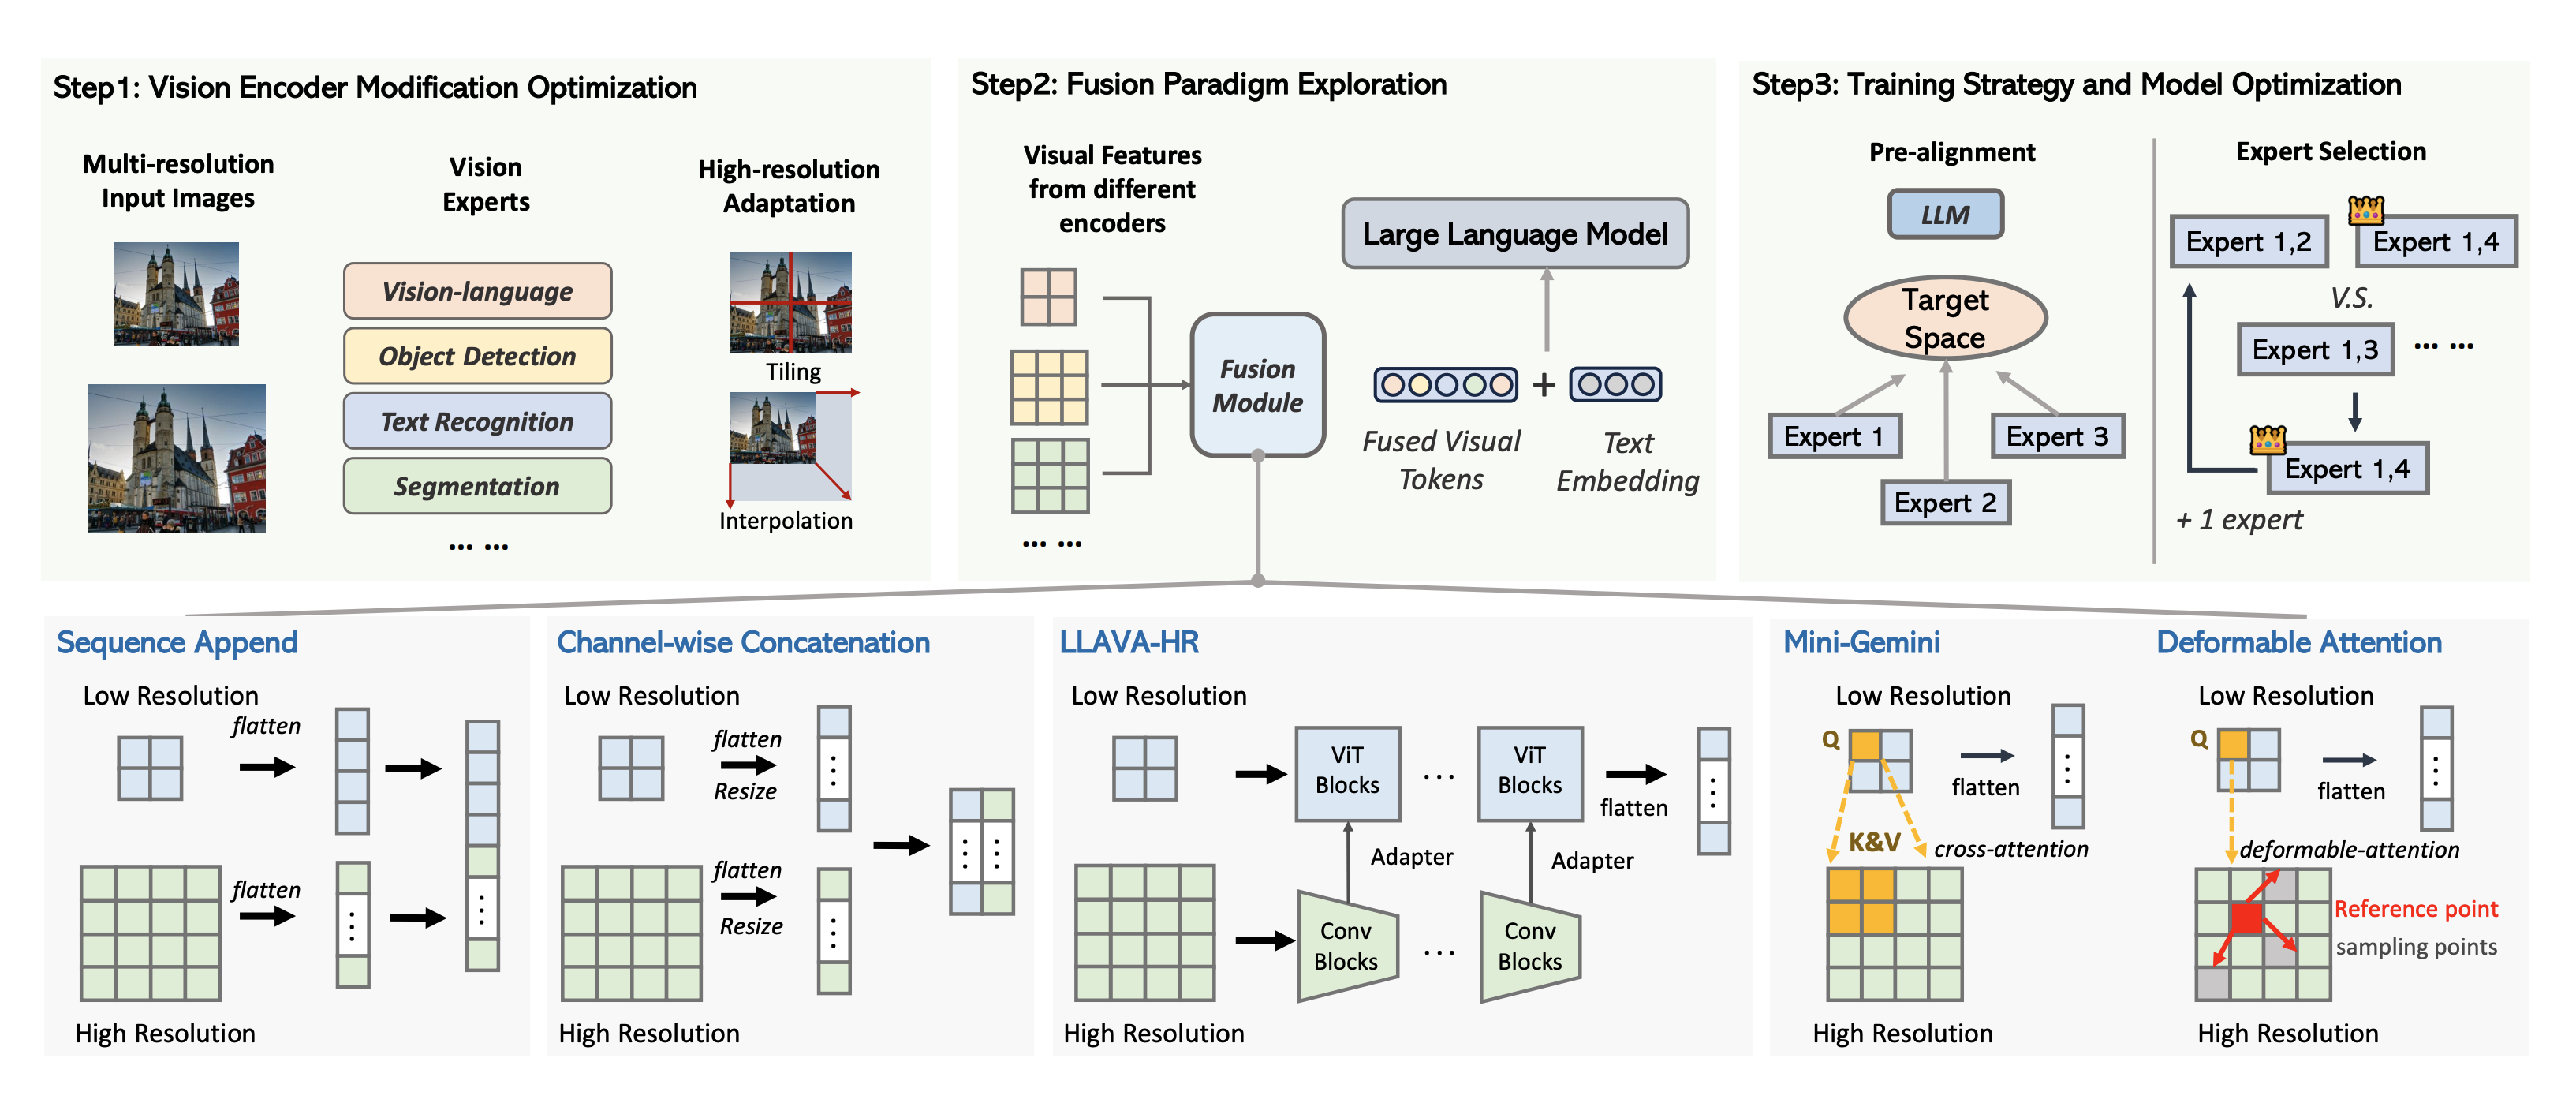
Eagle

Eagle: Exploring the Design Space for Multimodal LLMs with Mixture of Encoders

Min Shi, Fuxiao Liu, Shihao Wang, Shijia Liao, Subhashree Radhakrishnan, De-An Huang, Hongxu Yin, Karan Sapra, Yaser Yacoob, Humphrey Shi, Bryan Catanzaro, Andrew Tao, Jan Kautz, Zhiding Yu, Guilin Liu

ICLR 2025 Spotlight

Eagle 2

Eagle 2: Building Post-Training Data Strategies from Scratch for Frontier Vision-Language Models

Zhiqi Li, Guo Chen, Shilong Liu, Shihao Wang, Vibashan VS, Yishen Ji, Shiyi Lan, Hao Zhang, Yilin Zhao, Subhashree Radhakrishnan, Nadine Chang, Karan Sapra, et al.

arXiv 2025

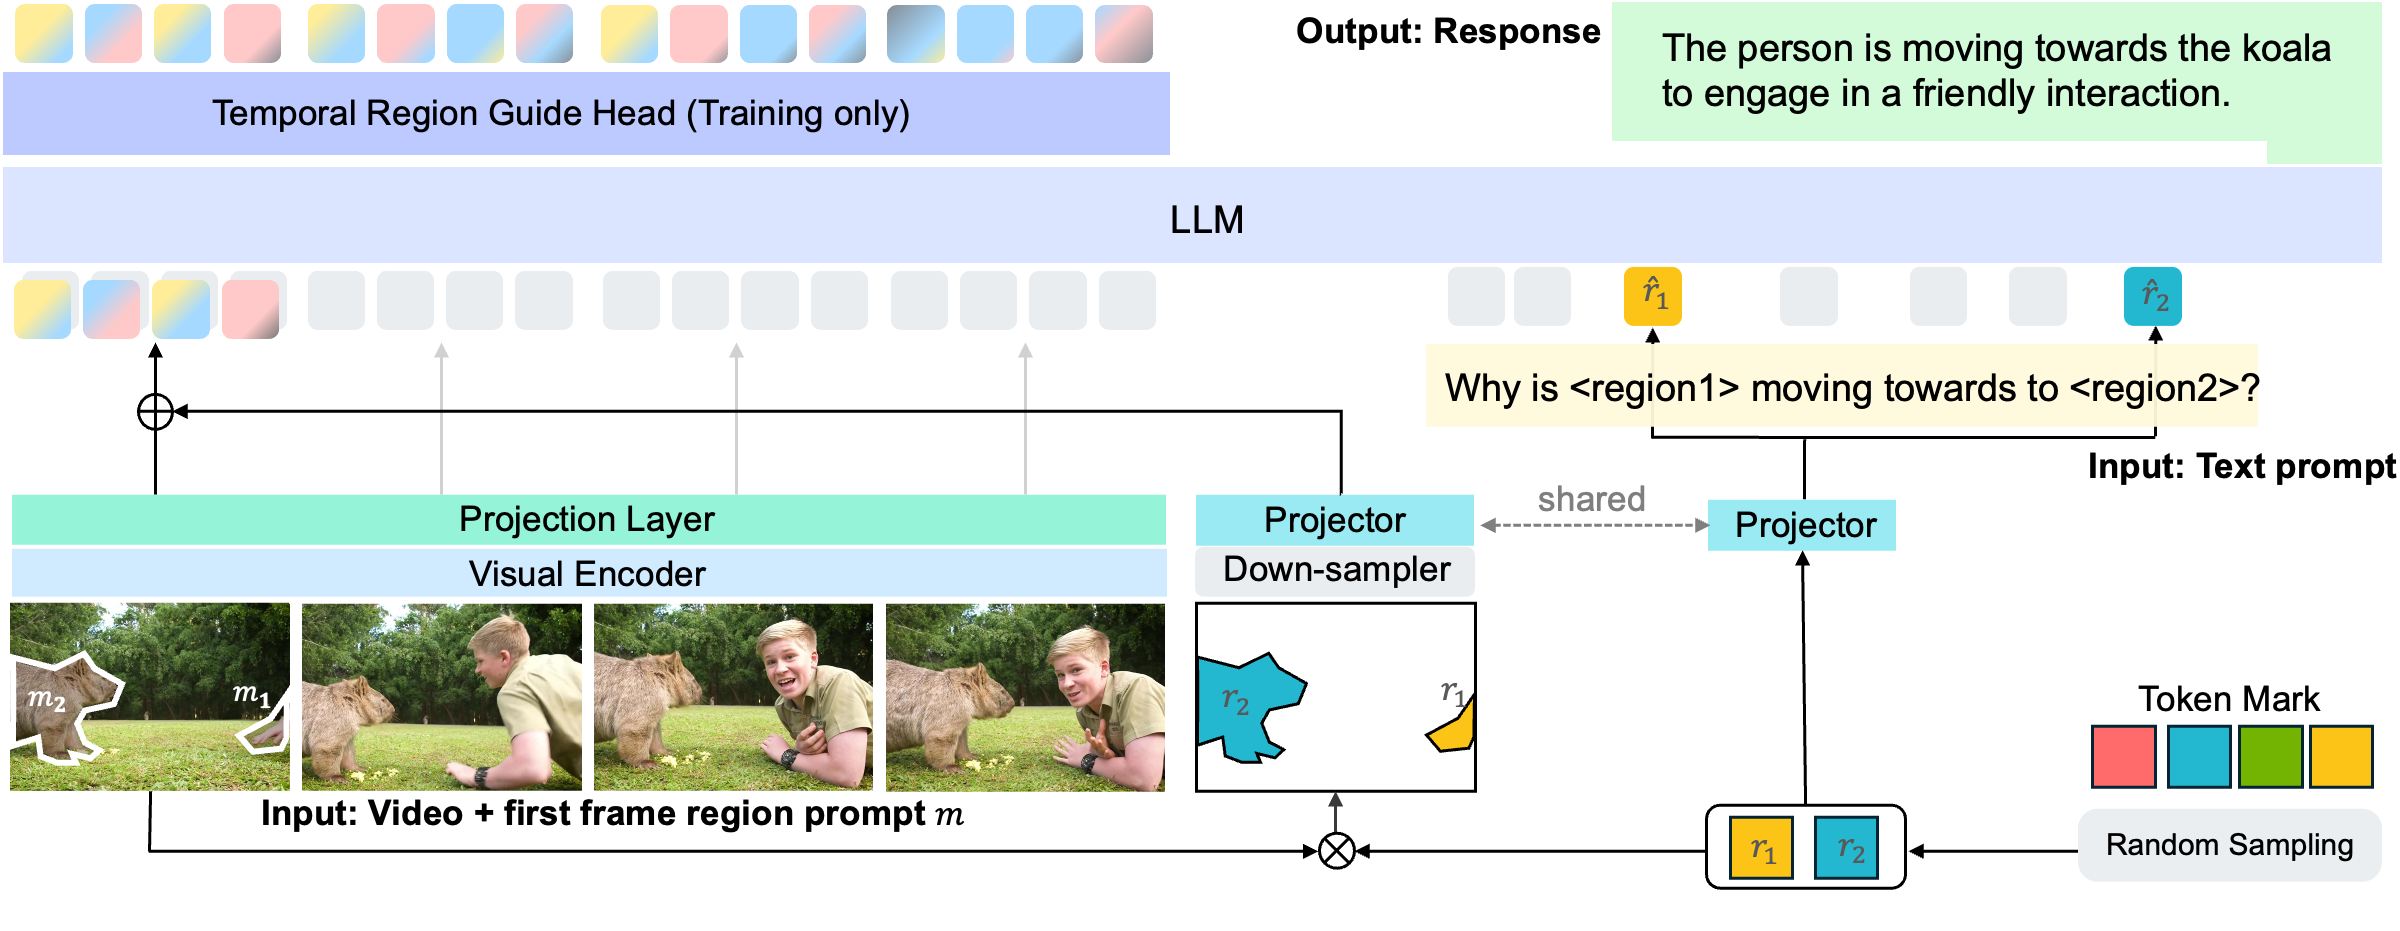
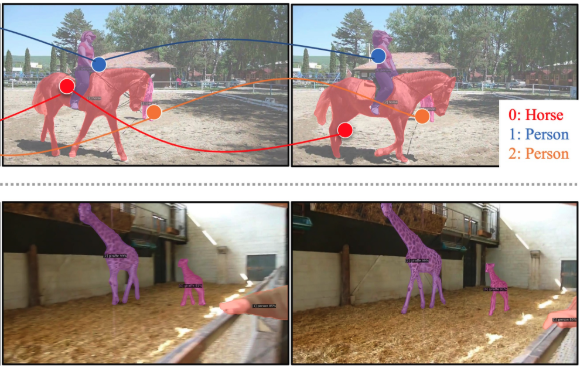
Omni-RGPT

Omni-RGPT: Unifying Image and Video Region-level Understanding via Token Marks

Miran Heo, Min-Hung Chen, De-An Huang, Sifei Liu, Subhashree Radhakrishnan, Seon Joo Kim, Yu-Chiang Frank Wang, Ryo Hachiuma

CVPR 2025

FRAG

FRAG: Frame Selection Augmented Generation for Long Video and Long Document Understanding

De-An Huang, Subhashree Radhakrishnan, Zhiding Yu, Jan Kautz

arXiv 2025

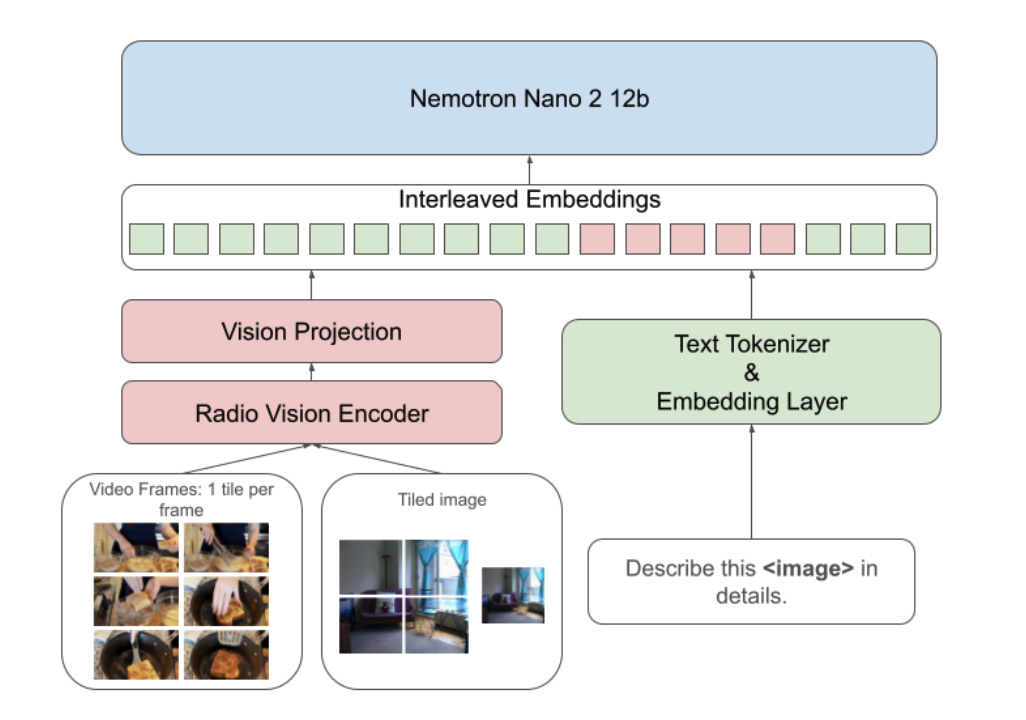
Nemotron Nano

NVIDIA Nemotron Nano V2 VL

Amala Sanjay Deshmukh, Kateryna Chumachenko, ..., Subhashree Radhakrishnan, et al.

arXiv 2025

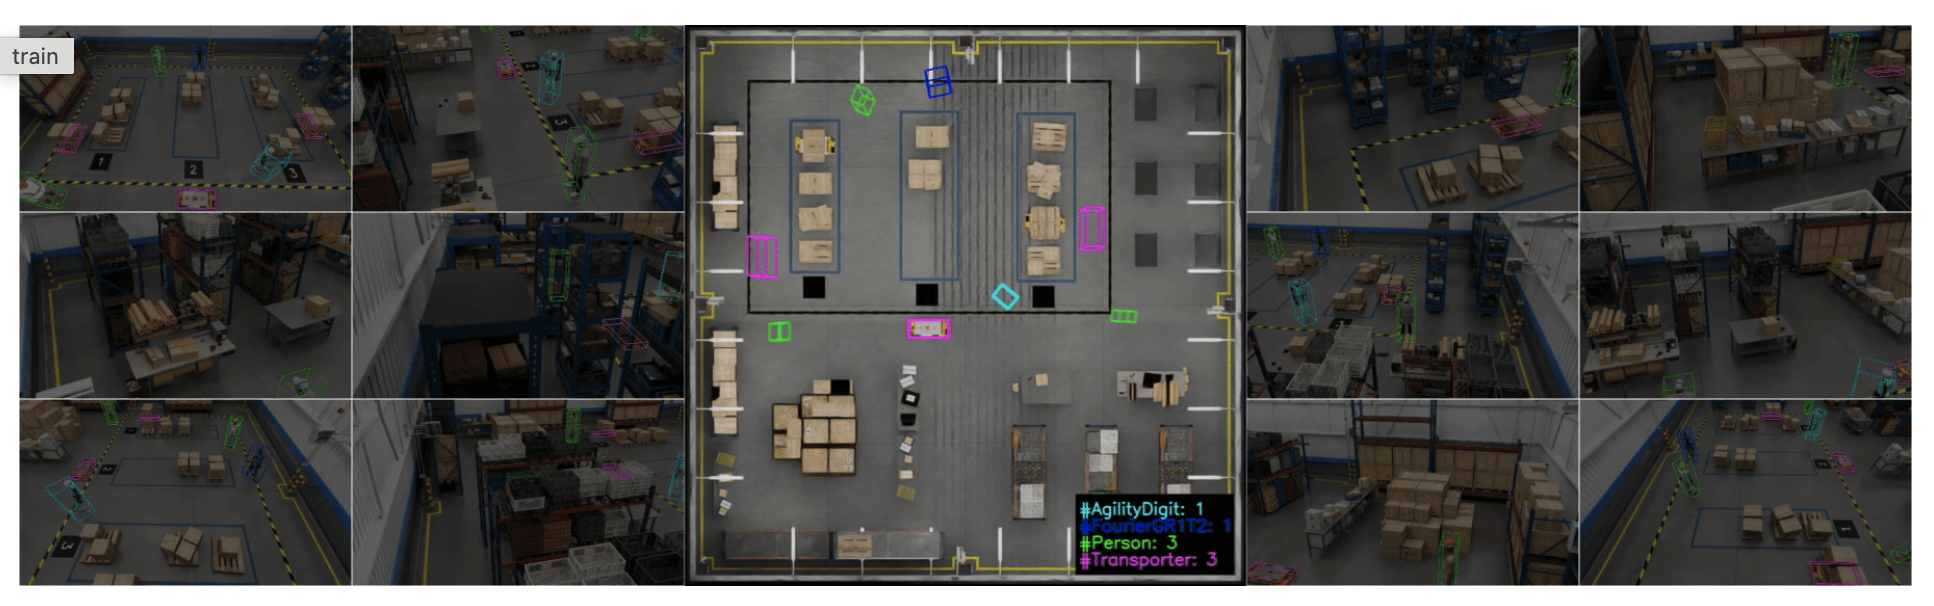
AI City Challenge

The 9th AI City Challenge

ICCV 2025 Workshop

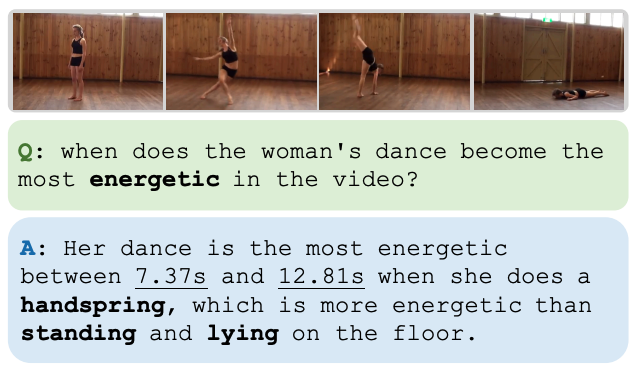
LITA

LITA: Language Instructed Temporal-Localization Assistant

De-An Huang, Shijia Liao, Subhashree Radhakrishnan, Hongxu Yin, Pavlo Molchanov, Zhiding Yu, Jan Kautz

ECCV 2024

Point Supervision

What is Point Supervision Worth in Video Instance Segmentation?

Shuaiyi Huang, De-An Huang, Zhiding Yu, Shiyi Lan, Subhashree Radhakrishnan, Jose M Alvarez, Abhinav Shrivastava, Anima Anandkumar

CVPR 2024 Workshop

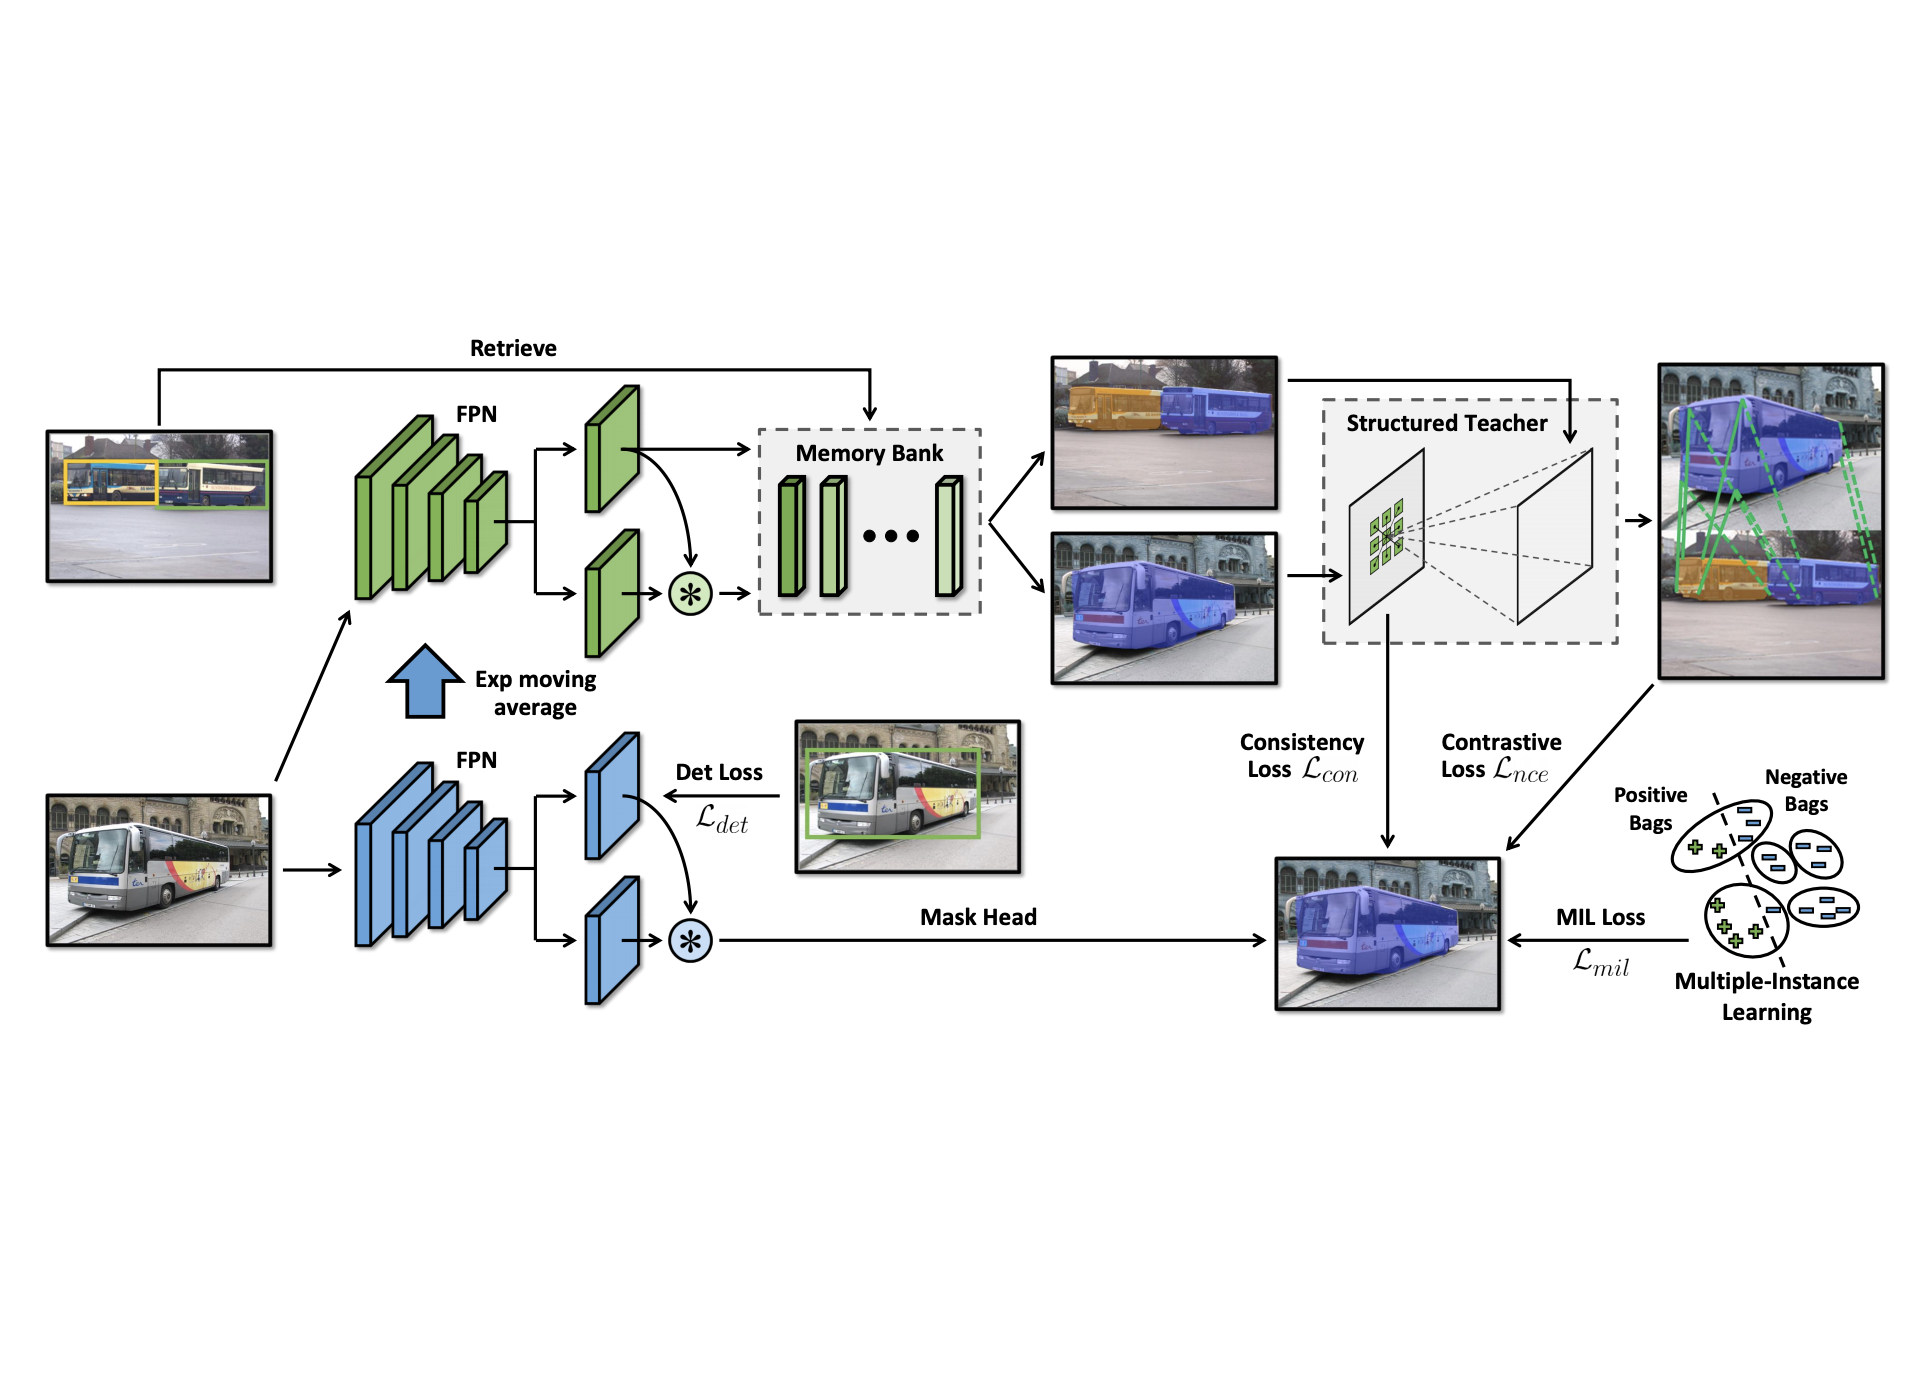
DiscoBox

DiscoBox: Weakly Supervised Instance Segmentation and Semantic Correspondence from Box Supervision

Shiyi Lan, Zhiding Yu, Christopher Choy, Subhashree Radhakrishnan, Guilin Liu, Yuke Zhu, Larry S Davis, Anima Anandkumar

ICCV 2021

Filed 25+ patents across multimodal learning, video understanding, and spatial AI.

Using Neural Networks to Perform Object Detection, Instance Segmentation, and Semantic Correspondence from Bounding Box Supervision

Zhiding Yu, Shiyi Lan, Chris Choy, Subhashree Radhakrishnan, Guilin Liu, Yuke Zhu, Anima Anandkumar

Determining Associations Between Objects and Persons Using Machine Learning Models

Parthasarathy Sriram, Fnu Ratnesh Kumar, Anil Ubale, Farzin Aghdasi, Yan Zhai, Subhashree Radhakrishnan

Training Object Detection Models Using Transfer Learning

Yu Wang, Farzin Aghdasi, Parthasarathy Sriram, Subhashree Radhakrishnan

Automatic Labeling and Segmentation Using Machine Learning Models

Subhashree Radhakrishnan, Partha Sriram, Farzin Aghdasi, Seunghwan Cha, Zhiding Yu

End-to-End Action Recognition in Intelligent Video Analysis and Edge Computing Systems

Subhashree Radhakrishnan, Farzin Aghdasi

Class Agnostic Object Mask Generation

Shiyi Lan, Zhiding Yu, Subhashree Radhakrishnan, Jose Manuel Alvarez Lopez, Animashree Anandkumar

Language Instructed Temporal Localization in Videos

De-An Huang, Shijia Liao, Subhashree Radhakrishnan, Hongxu Yin, Pavlo Molchanov, Zhiding Yu, Jan Kautz

Language Instructed Temporal Localization in Video Using Image Tokens, Video Tokens, and/or Soft Cross Entropy Loss

De-An Huang, Shijia Liao, Subhashree Radhakrishnan, Zaid Pervaiz Bhat, Zhiding Yu, Parthasarathy Sriram, Jan Kautz

Techniques for Implementing Multimodal Large Language Models with Mixtures of Vision Encoders

Guilin Liu, Zhiding Yu, Min Shi, Fuxiao Liu, Shihao Wang, Shijia Liao, Subhashree Radhakrishnan, De-An Huang, Hongxu Yin, Karan Sapra, Bryan Catanzaro, Andrew J Tao, Jan Kautz

Auto-Labeling Systems and Applications for Open-Set and Out-of-Domain Segmentation

Subhashree Radhakrishnan, Ramanathan Arunachalam, Farzin Aghdasi, Zhiding Yu, Shiyi Lan

Object Segmentation Using Machine Learning for Autonomous Systems and Applications

Alperen Degirmenci, Jiwoong Choi, Zhiding Yu, Ke Chen, Shubhranshu Singh, Yashar Asgarieh, Subhashree Radhakrishnan, James Skinner, Jose Manuel Alvarez Lopez

Point-Level Supervision for Video Instance Segmentation

Zhiding Yu, Shuaiyi Huang, De-An Huang, Shiyi Lan, Subhashree Radhakrishnan, Jose M Alvarez Lopez, Anima Anandkumar